The Layer You're Comparing Doesn't Matter
Hacker News is arguing over whether local models can replace Claude for coding, and four hundred comments later no one is questioning the premise. What decides whether you can switch has never been how good the model is—it’s the harness wrapped around it.
These past few days, a question has been sitting on the Hacker News front page with more than a thousand upvotes and four hundred replies: “Has anyone actually replaced Claude / GPT with local models for daily coding?” The comment section is torn. One side says local is cheaper, private, and works offline—someone calculated that two RTX 3090s pay for themselves against cloud subscriptions in three or four years. The other side says local still falls short and you have to crawl back to the cloud when it really matters.
After four hundred comments, nobody is questioning the question itself. Buried in it is an assumption: what decides whether you can switch is whether the model is good enough. As if the switch is made the moment local model scores catch up. I write code with agents every day, and my read is the opposite—most people are staring at the wrong layer.
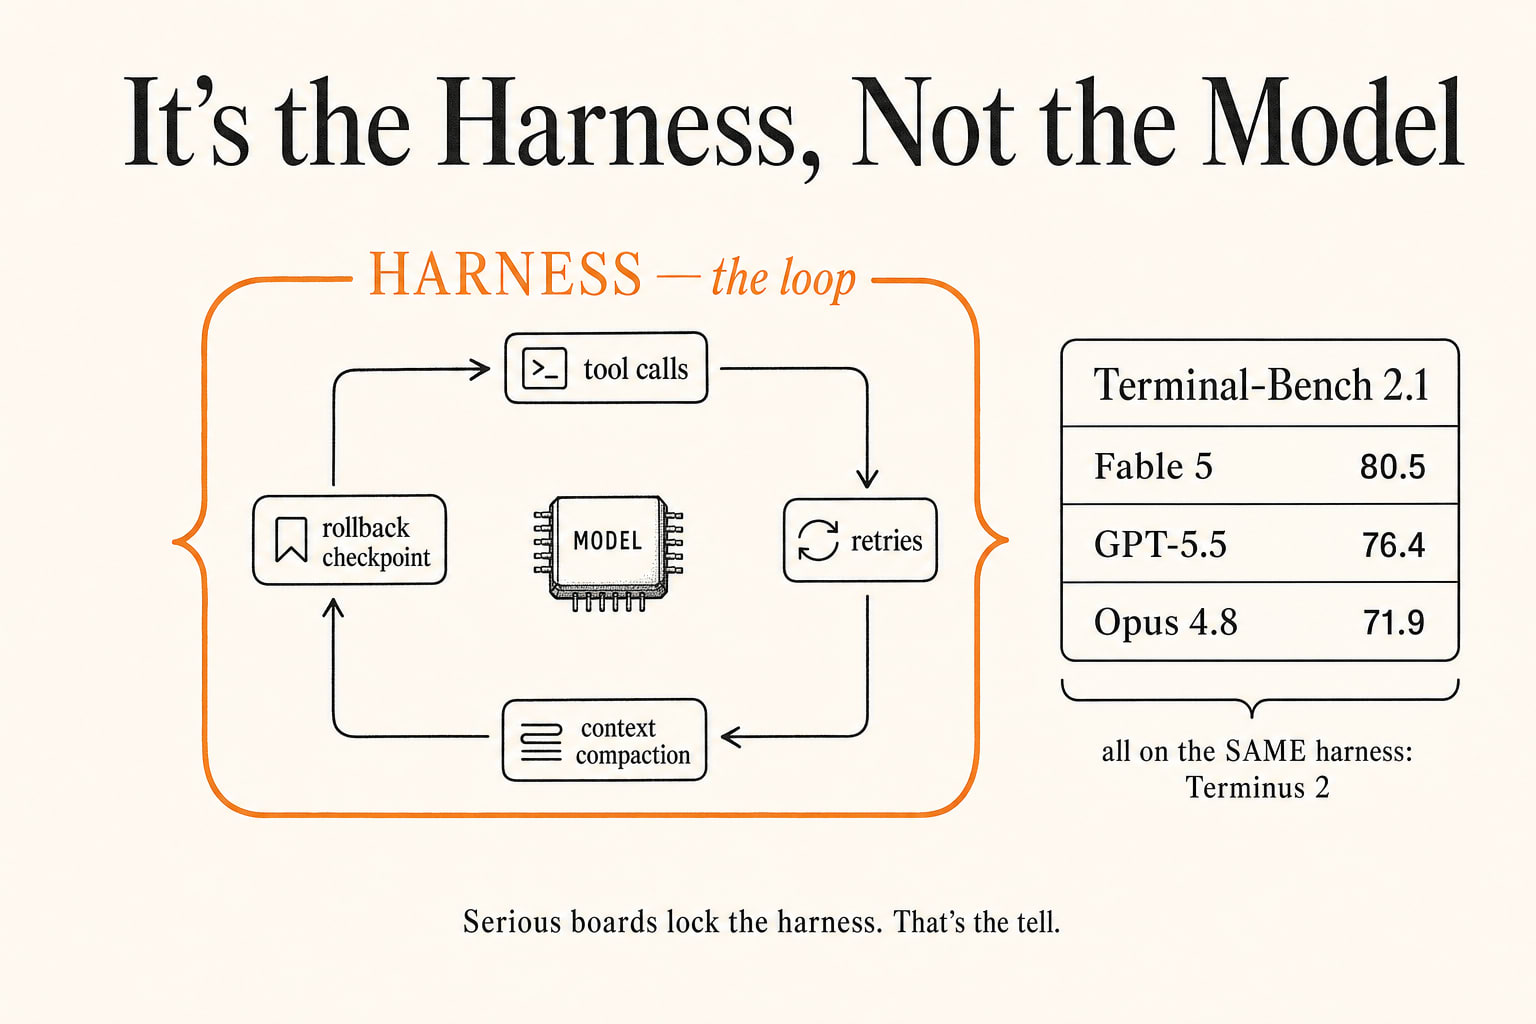
Agentic coding has never been as simple as “the model spits out a piece of code.” It’s a loop: read the repo, call tools, edit files, run tests, read the error, edit again, run again. Over a real task, there are dozens or hundreds of tool calls, and the model is just the component being invoked over and over inside that loop. What actually decides whether this long run holds together—or gets itself confused around step 30—is the layer wrapped around the model. The industry calls it the harness (the scaffolding: the set of programs that connects the model to tools, manages context, and handles retries and verification; Claude Code and Codex CLI are both harnesses).
The cleanest evidence is hidden in the benchmark designs themselves. In this edition of Terminal-Bench 2.1 (the leaderboard that tests agents doing real work in a terminal), Fable 5 leads at 80.52, GPT-5.5 at 76.40, and Opus 4.8 at 71.91. But the names aren’t what to watch; what to watch is that line in the methodology: all models are tested through the same harness, called Terminus 2. Why lock down the harness? Because the designers know the harness is a confounding factor that can drown out model differences—if you don’t fix it, you’re not measuring whose model is stronger; you’re measuring whose shell is better. The fact that serious leaderboards must lock down the harness is itself hard proof that the harness matters as much as the model.
This is even more obvious in daily work. Leaderboards like SWE-Bench measure “given a neatly packaged problem, can the model solve it”—the model’s intelligence in a vacuum. But your real job is not solving one problem; it’s changing one spot in a 200,000-line repo you’ve never read without breaking three others, while holding context for hours. None of those leaderboards measure any of that. In the HN thread, the people using local models don’t keep saying “it can’t write a function”—a 30B local model has long been enough to write a single function. What they say is that it’s like a junior engineer you have to guide step by step: you have to lay out the architecture for it, cut the task into the tiniest pieces, and even remember to delete the debug statements yourself. These are all failures of “staying on course across dozens of consecutive steps”—failures of the loop, not failures of intelligence. And without a good harness holding things together, frontier models drift off course too.
Once you see this clearly, local vs. cloud becomes a different question. The harness does all the unglamorous dirty work—writing the model’s output accurately into files, retrying automatically on errors, compressing context before it overflows, keeping a revertible checkpoint after each edit. This layer happens to be open, and something you can change yourself. When I swap the underlying model in my own agent, the output often barely changes; but the time I rewrote the verification step—making it run its own checks after every edit and roll back if they failed—the whole system’s usability jumped visibly. The model is becoming a utility like water or electricity; the harness is the lever you can actually hold in your hand.
So my one-sentence answer to that HN question is: don’t ask whether local models are good enough to replace Claude; first ask whether your loop is stable enough—stable enough that you can plug any model in and it keeps running. If the harness is rough, even the strongest cloud model only moves your failure point a few steps further out; if the harness is solid, the day local models can take over will come sooner than the leaderboards tell you.
What’s worth replacing has never been the model. It’s the layer you wrap around it.